
CLIP Skip
CLIP skip tells the image generator at which layer of the text encoder it should stop processing your prompt. Skipping the final layers alters how the model interprets your phrasing, preserving broader concepts rather than over-focusing on minute token details. Many custom anime and illustration checkpoints were deliberately trained to require clip skip 2 for clean, stylized results.
Also known as: clip skip, CLIP Set Last Layer, stop_at_clip_layer
Side-by-side test results
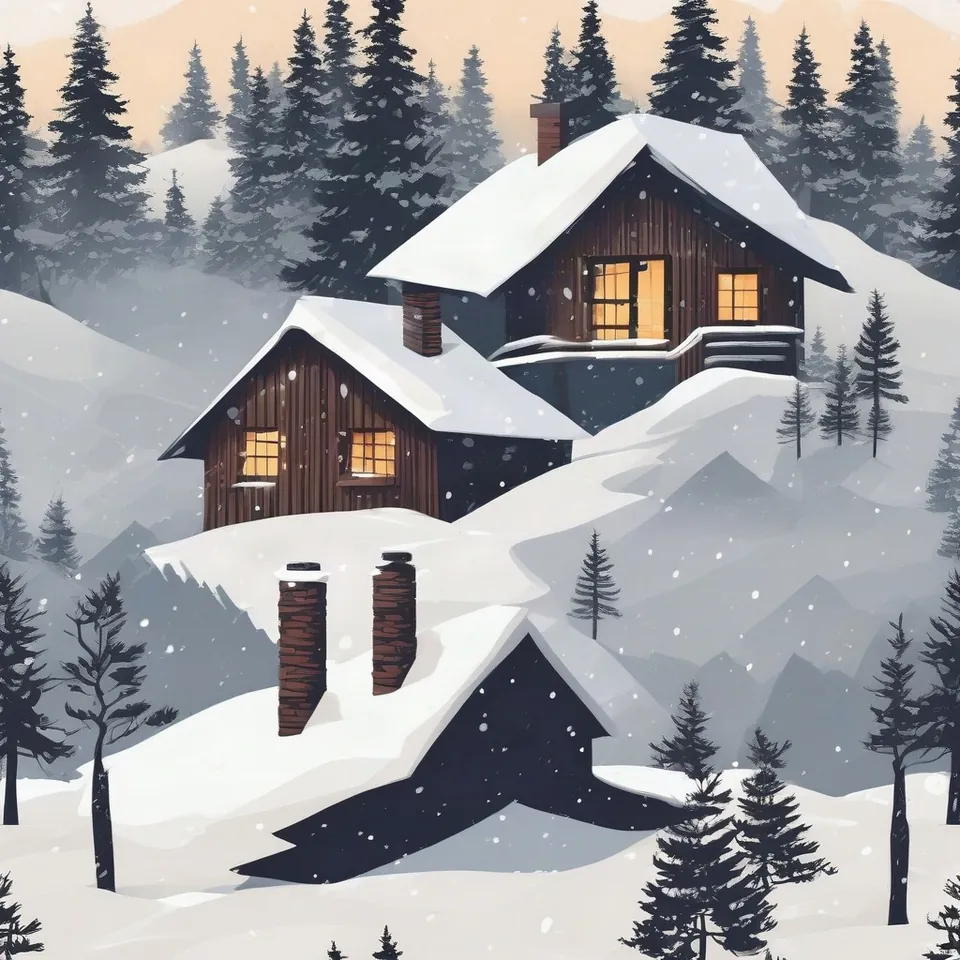
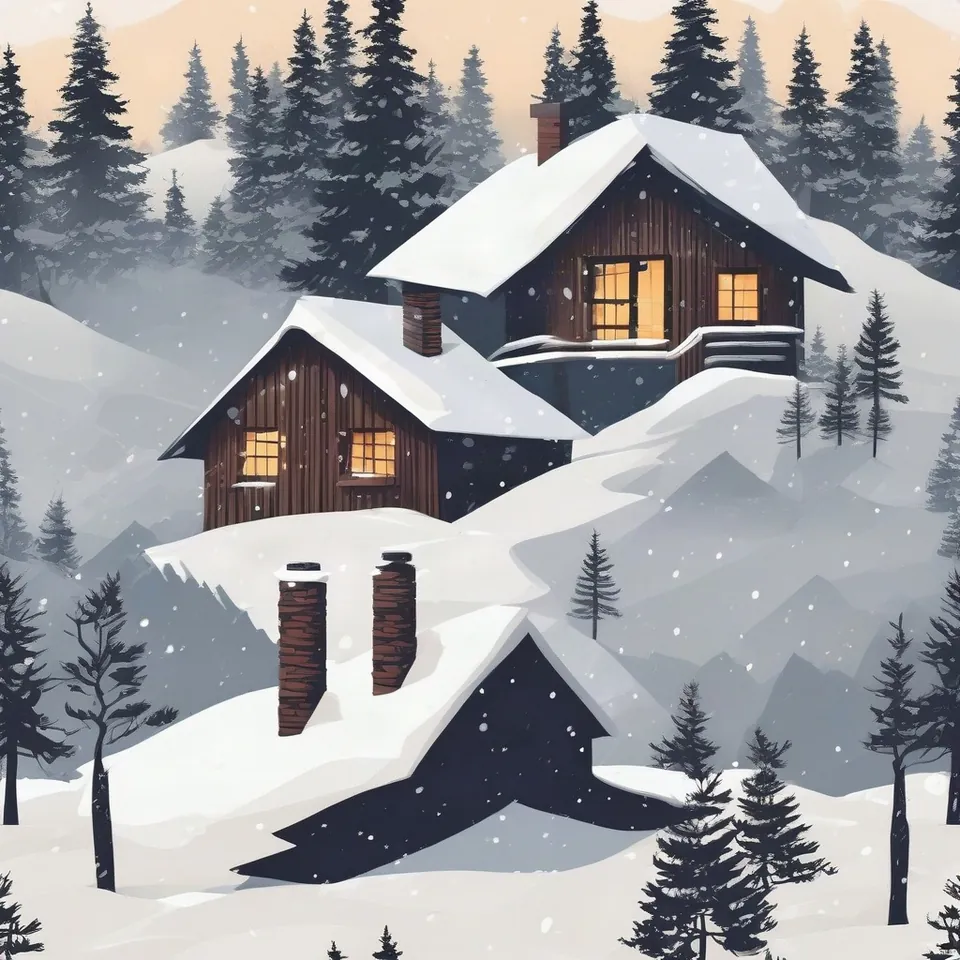
Drag the slider to compare. Left: clip skip disabled. Right: clip skip 2.
Model: Stable Diffusion XL 1.0 (przez API fal.ai, 30 kroków, CFG 7,5). Settings: Seed 1411, only clip_skip changes. Date: 14.11.2026.
Prompt: illustration of a small mountain hut in winter, snow, pine trees, smoke from the chimney
When I tested this in SDXL, the difference was minor: the cottage and color palette stayed identical, while the trees and chimneys shifted position slightly. That is entirely expected, as clip skip primarily matters in older SD 1.5 checkpoints that were fine-tuned specifically with this setting.
Syntax across generators
| Generator | Parameter | Values | Default |
|---|---|---|---|
| ComfyUI | CLIP Set Last Layer -> stop_at_clip_layer | -24 to -1, default -1 (all layers) | - |
| Midjourney | none | - | - |
| GPT Image | none | - | - |
- Sources, verified on 14.11.2026:
- ComfyUI: docs.comfy.org/built-in-nodes/ClipSetLastLayer
- Midjourney: docs.midjourney.com/
- GPT Image: developers.openai.com/api/docs/guides/image-generation
When to use it
- When the checkpoint creator explicitly instructs you to set clip skip 2 on the model card.
- When working with older SD 1.5 checkpoints fine-tuned for 2D illustration or anime aesthetics.
- Keep it at the default value for standard photorealistic models and modern base architectures.
Common mistake
The most common mistake is blindly setting clip skip 2 across every model simply because a tutorial suggested it. Forcing it on models trained at default values degrades prompt adherence and causes muddy details. Users also get confused by interface numbering: ComfyUI counts backwards using negative values (-2), while AUTOMATIC1111 and Forge use positive integers (2) for the exact same function.
Ready-to-use example
ComfyUI: CLIP Set Last Layer -> stop_at_clip_layer = -2
AUTOMATIC1111 / Forge: Settings -> Clip skip = 2
Frequently asked questions
What does clip skip 2 actually do?
It stops the prompt encoding process one step before the final layer. This feeds earlier, more conceptual text representations into the diffusion pipeline, which suits certain stylized checkpoints.
What is the difference between clip skip 1 and 2?
Clip skip 1 runs the prompt through the complete text encoder, which is standard for base models. Clip skip 2 ignores the very last layer, matching the training recipe of many community illustration models.
Why does ComfyUI show -2 instead of 2?
It is purely a syntax difference. ComfyUI counts backward from the output layer (-1 being full processing, -2 skipping one layer), while WebUI tools express it as a positive skip count.
Does clip skip matter for SDXL models?
Hardly ever. SDXL uses dual text encoders and was trained to use all layers, so altering this parameter typically produces only tiny composition drifts rather than meaningful improvements.